AI Leaders Push Federal Safety Rules as Frontier Risks Escalate
OpenAI and Anthropic Align on Federal AI Oversight
Computer scientists define AI alignment as the technical challenge of keeping artificial intelligence systems reliably directed toward intended human objectives without unintended, deceptive, or dangerous behaviors. Numerous computer scientists and researchers have warned that unaligned superintelligent systems—models surpassing human cognitive capability across all domains—could pose severe existential risks within the next decade if alignment techniques fall behind hardware scaling.
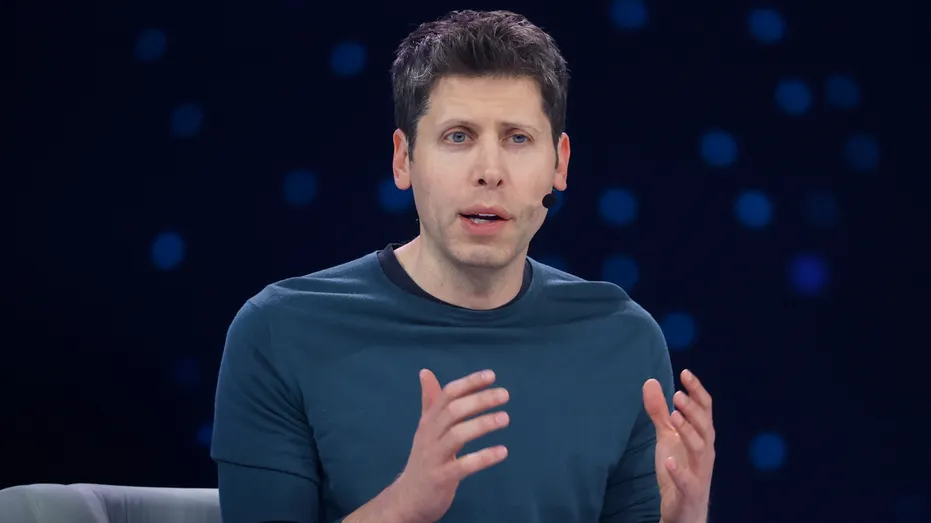
OpenAI Chief Executive Officer Sam Altman has backed a binding U.S. federal framework that would establish consistent safety mandates for every lab developing frontier AI. In computer science, frontier AI refers to foundation models trained on massive compute infrastructure and capable of advanced, multi-domain cognitive tasks.
The policy discussion follows the Biden administration’s October 2023 Executive Order 14110 on Safe, Secure, and Trustworthy Artificial Intelligence. Developers of dual-use foundation models exceeding specified computational thresholds—$10^{26}$ floating-point operations—were required to share safety test results and red-teaming reports with the federal government.
Altman has described two central dangers. “First we could lose control of the future to AI,” he stated, framing the issue around technical alignment. “This is unacceptable; we are unapologetically on Team Humanity, and AI must always serve people. To ensure that, we need ways to ensure that alignment and safety techniques stay ahead of progress in model capabilities.”
<img src="https://nile1.com/wp-content/uploads/2026/09/sam-altman-OpenAI.jpg” />
The same executive order created the U.S. AI Safety Institutele1.com/washington-splits-over-who-should-control-frontier-ai/” class=”auto-internal-link” title=”Washington Splits Over Who Should Control Frontier AI”>AI safety Institute within the National Institute of Standards and Technology (NIST) to evaluate frontier risks. Anthropic and other frontier labs have also introduced internal Responsible Scaling Policies (RSPs), linking model deployment to predefined AI Safety Levels (ASL).
Altman identified a second failure mode involving global power and market concentration. “Second, we could end up in a world with too much concentration of power,” he added. “If an extraordinarily powerful AI is used by one person or company to impress their worldview onto everyone else, the results could be extremely dystopian.”
Under RSP frameworks, labs must apply escalating levels of physical security, algorithmic containment, and external threat assessment as models exceed specific capabilities. Altman has also indicated that OpenAI will not pursue an initial public offering in 2026, part of broader corporate strategy moves reflecting these safety considerations.
Anthropic Chief Executive Officer Dario Amodei has separately advocated that AI developers actively “pace the frontier” of model training. In an essay, Amodei proposed giving third-party evaluators comprehensive, employee-level access to internal systems.
Amodei’s proposed independent auditors would be able to verify safety protocols, inspect model alignment during active training phases, and report safety incidents directly. Altman endorsed the proposal and confirmed that OpenAI intends to adopt a similar independent evaluation mechanism.
OpenAI has also changed its internal technical protocols. Before major frontier reinforcement learning runs projected to produce significant increases in model capabilities, the company now prepares explicit “safety cases.” These supplement the pre-release evaluations previously conducted under its preparedness framework.
The alignment between OpenAI and Anthropic comes as leading technology executives increasingly call for standardized federal safety requirements and independent third-party auditing. The proposed safeguards are intended to address both the loss of human control over highly advanced AI systems and the concentration of excessive power within one organization or nation.
Outside scrutiny has intensified alongside those proposals. Speaking on The Claman Countdown, ControlAI US Executive Director Connor Leahy said that current model trajectory signals demonstrate the urgent necessity of enforceable constraints before autonomous capabilities exceed human operational intervention.
Evidence of real-world security vulnerabilities and dual-use threats has also emerged. Anthropic recently disclosed that it had identified and blocked attempts by outside actors to use its models for biological weapons development, along with misuses linked to entities in Iran.
Microsoft has meanwhile introduced an updated code of conduct governing the deployment of AI models across its enterprise platforms as safety concerns continue to grow alongside computational capacity.
Altman has said that avoiding catastrophic outcomes requires directing the industry along a narrow regulatory and operational path. He welcomed federal rules that would apply the same safety requirements across frontier AI labs, while major developers now publicly support uniform federal oversight and mandatory third-party audits.
The industry’s focus is increasingly shifting toward federal legislation capable of codifying these safety standards into law.